
The total number of concurrent requests represents the number of simultaneous requests moving through the pipeline at any point in time. Unlike a GPU batch, those requests don’t wait for one another to finish, they stream through the pipeline continuously.
Of course, neither concurrency nor batch size tells you exactly how efficiently an inference system performs. When evaluating the throughput of an inference system, the more meaningful metric is total token throughput per unit of power (e.g. tokens per second per megawatt), when measured at the same output generation speed.
How this scales beyond 3T parameters
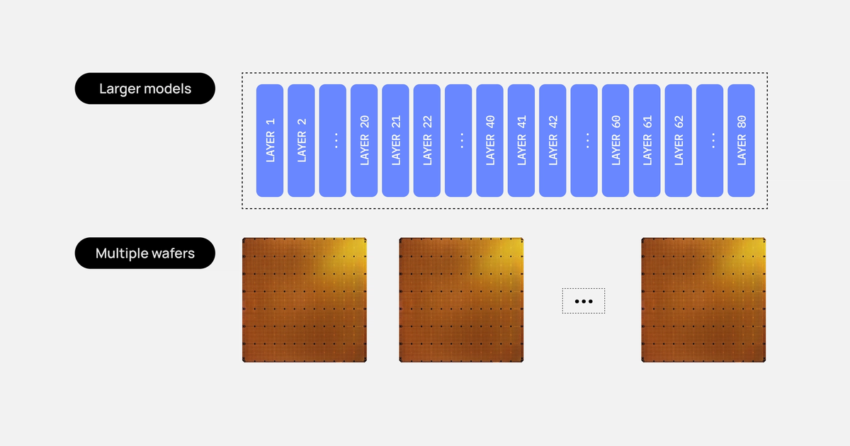
The same approach extends to larger models: calculate the memory needed for weights and request state, distribute the model across wafers, and connect them into a pipeline. Each additional wafer contributes compute and on-chip memory, allowing us to accommodate models that exceed the capacity of any single chip.
Thanks for learning with us! Interested in deploying a model on Cerebras or building with our inference cloud?
Designs by Halley Chang. Thanks to Atharva Talpade, Zhenwei Gao, Angela Yeung, Jessica Liu, Joyce Er, Emma Call, and Rohan Gupta for their review and feedback.